My DEF CON 2026 Training Experience in Singapore
- Categories:
- notes
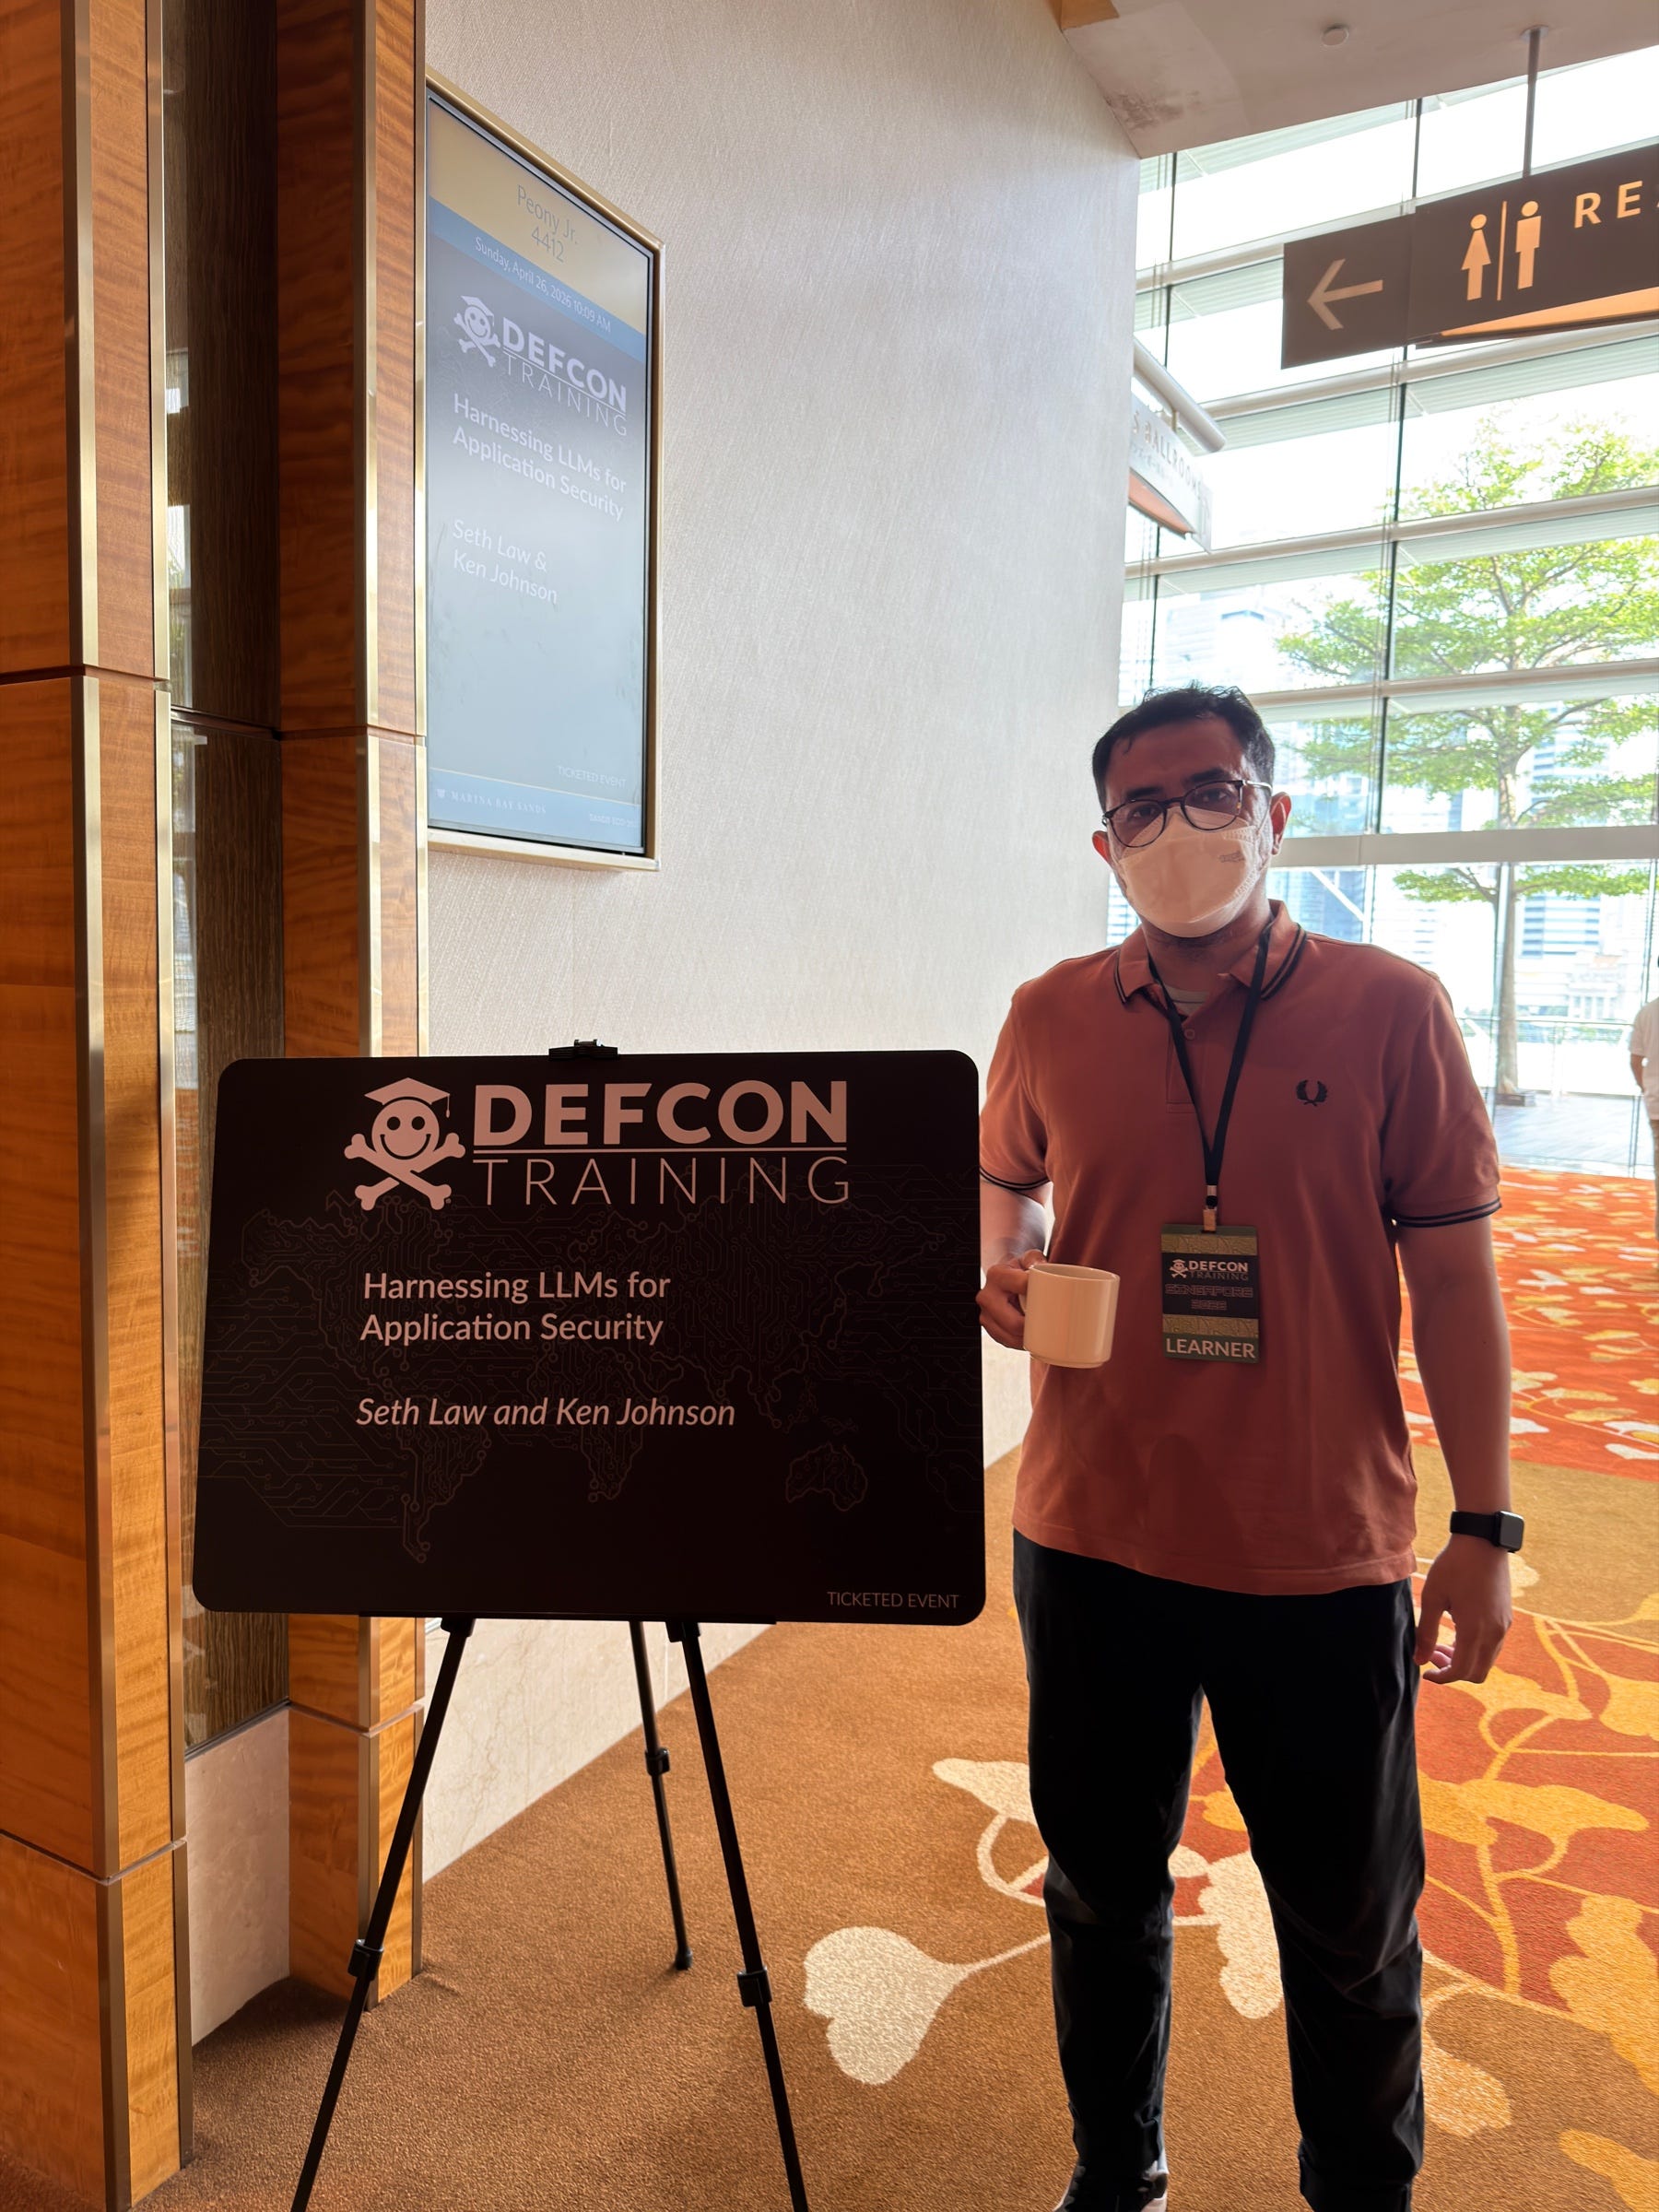
Last month, I attended DEF CON training: Harnessing LLMs for Application Security.
From this training, I learned a ton about LLM fundamentals such as inference, temperature, top-p/top-k sampling, prompt engineering, RAG, and agentic AI.
The training also covered how to use LLMs to help secure applications and how to secure LLM-based applications themselves such as prompt injection protection.
But the insight that stuck with me most is about the relationship between LLM probability and security:
LLMs don’t reason. They predict.
For example, if the training data are only consists the following sentences:
- I love AppSec
- You love AppSec
- We love AppSec
LLMs will predict next word after love is 100% AppSec.
This means:
- They predict what secure looking code resembles
- Common vulnerabilities-> often detected
- Well-known fixes -> often suggested
- Repeated code patterns -> higher confidence
- Business logic flaws -> frequently missed
- Authz/Authn edge cases -> inconsistent
- Novel vulnerabilities -> invisible
LLMs don’t find vulnerabilities, they find patterns that resemble vulnerabilities.